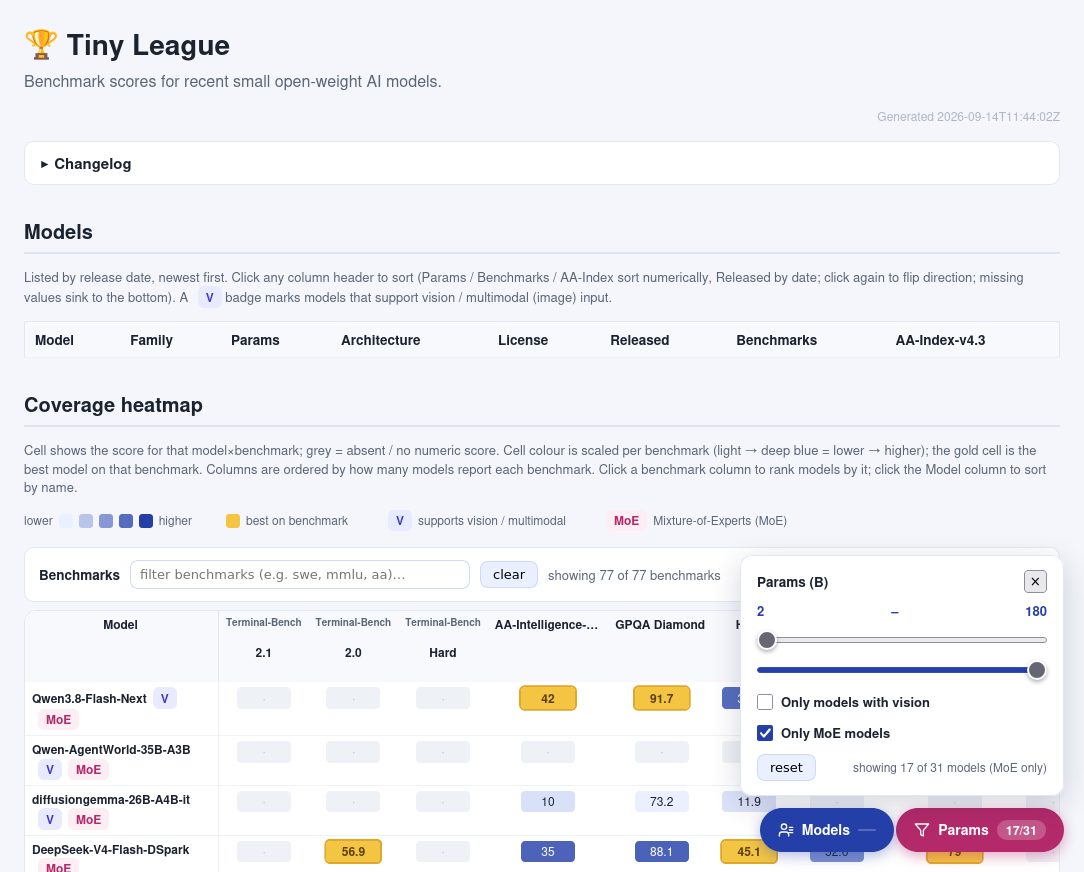
So I built Tiny League for those of use who care about small models. By small, I'm aiming at 3-200B, which is a range that I consider both capable and able to run at home (for those who have unified memory like mac, strix or spark)
I'm limiting the model list to models released after April and excluding models that are trained for specific use-cases.
Appreciate all sorts of feedback :)
1. Bug: checking "Only MoE models" leaves the list empty.
2. I'd like to see the number of active parameters for MoE models. You could make it a parenthetical in the parameters column.
3. Practical RAM/VRAM requirements would be valuable. For example, see this thread on K2 Horizon: https://old.reddit.com/r/LocalLLaMA/comments/1wg4a0u/k2_hori.... It is important information that isn't obvious from the model size.
The next level of time and effort would be to benchmark the models yourself. I am interested in x86-64 CPU benchmarks, but that's probably niche and there will be more interest in benchmarks on a modest GPU. The most common amount of VRAM on Steam (https://store.steampowered.com/hwsurvey/Steam-Hardware-Softw...) is 16 GB, followed closely by 8 GB.
1. works fine for me, are you sure you don't have any other filters active that might result in 0 models?
2. good idea, a few people have requested that. It becomes a little bit more difficult when models have engrams, but I will consider!
3. There are some tools to do that, I personally don't like them. I understand the convenience but I am staying away from that. There are many factors at play, not all models work the same way, even if they use the same VRAM. Not to speak of using quants and how each quant may affect a model differently
This is what I see when I check the MoE checkbox. The list at the top of the page has no models: https://paste.dbohdan.com/1nagxp2-s90bk/screenshot.png.